
Collaborating with industry leaders


HIRO PEaaS STACK
Learn more
Sized to the site
Hang the unit on the wall of an office, or stack them in a server closet. Add more units if the site needs more compute.
Flexible configuration
Fill the unit with the GPUs, CPUs and storage your workload needs. Use server modules from any vendor that builds to the open COM-HPC standard.
Low power use
A fully loaded unit draws under 3 kW. Plug it into an ordinary 16 A circuit, with no upgrade to the site’s power supply.
Fans or water
Cool the unit with fans, or connect it to the building’s water loop.
Learn more
Autonomous sites
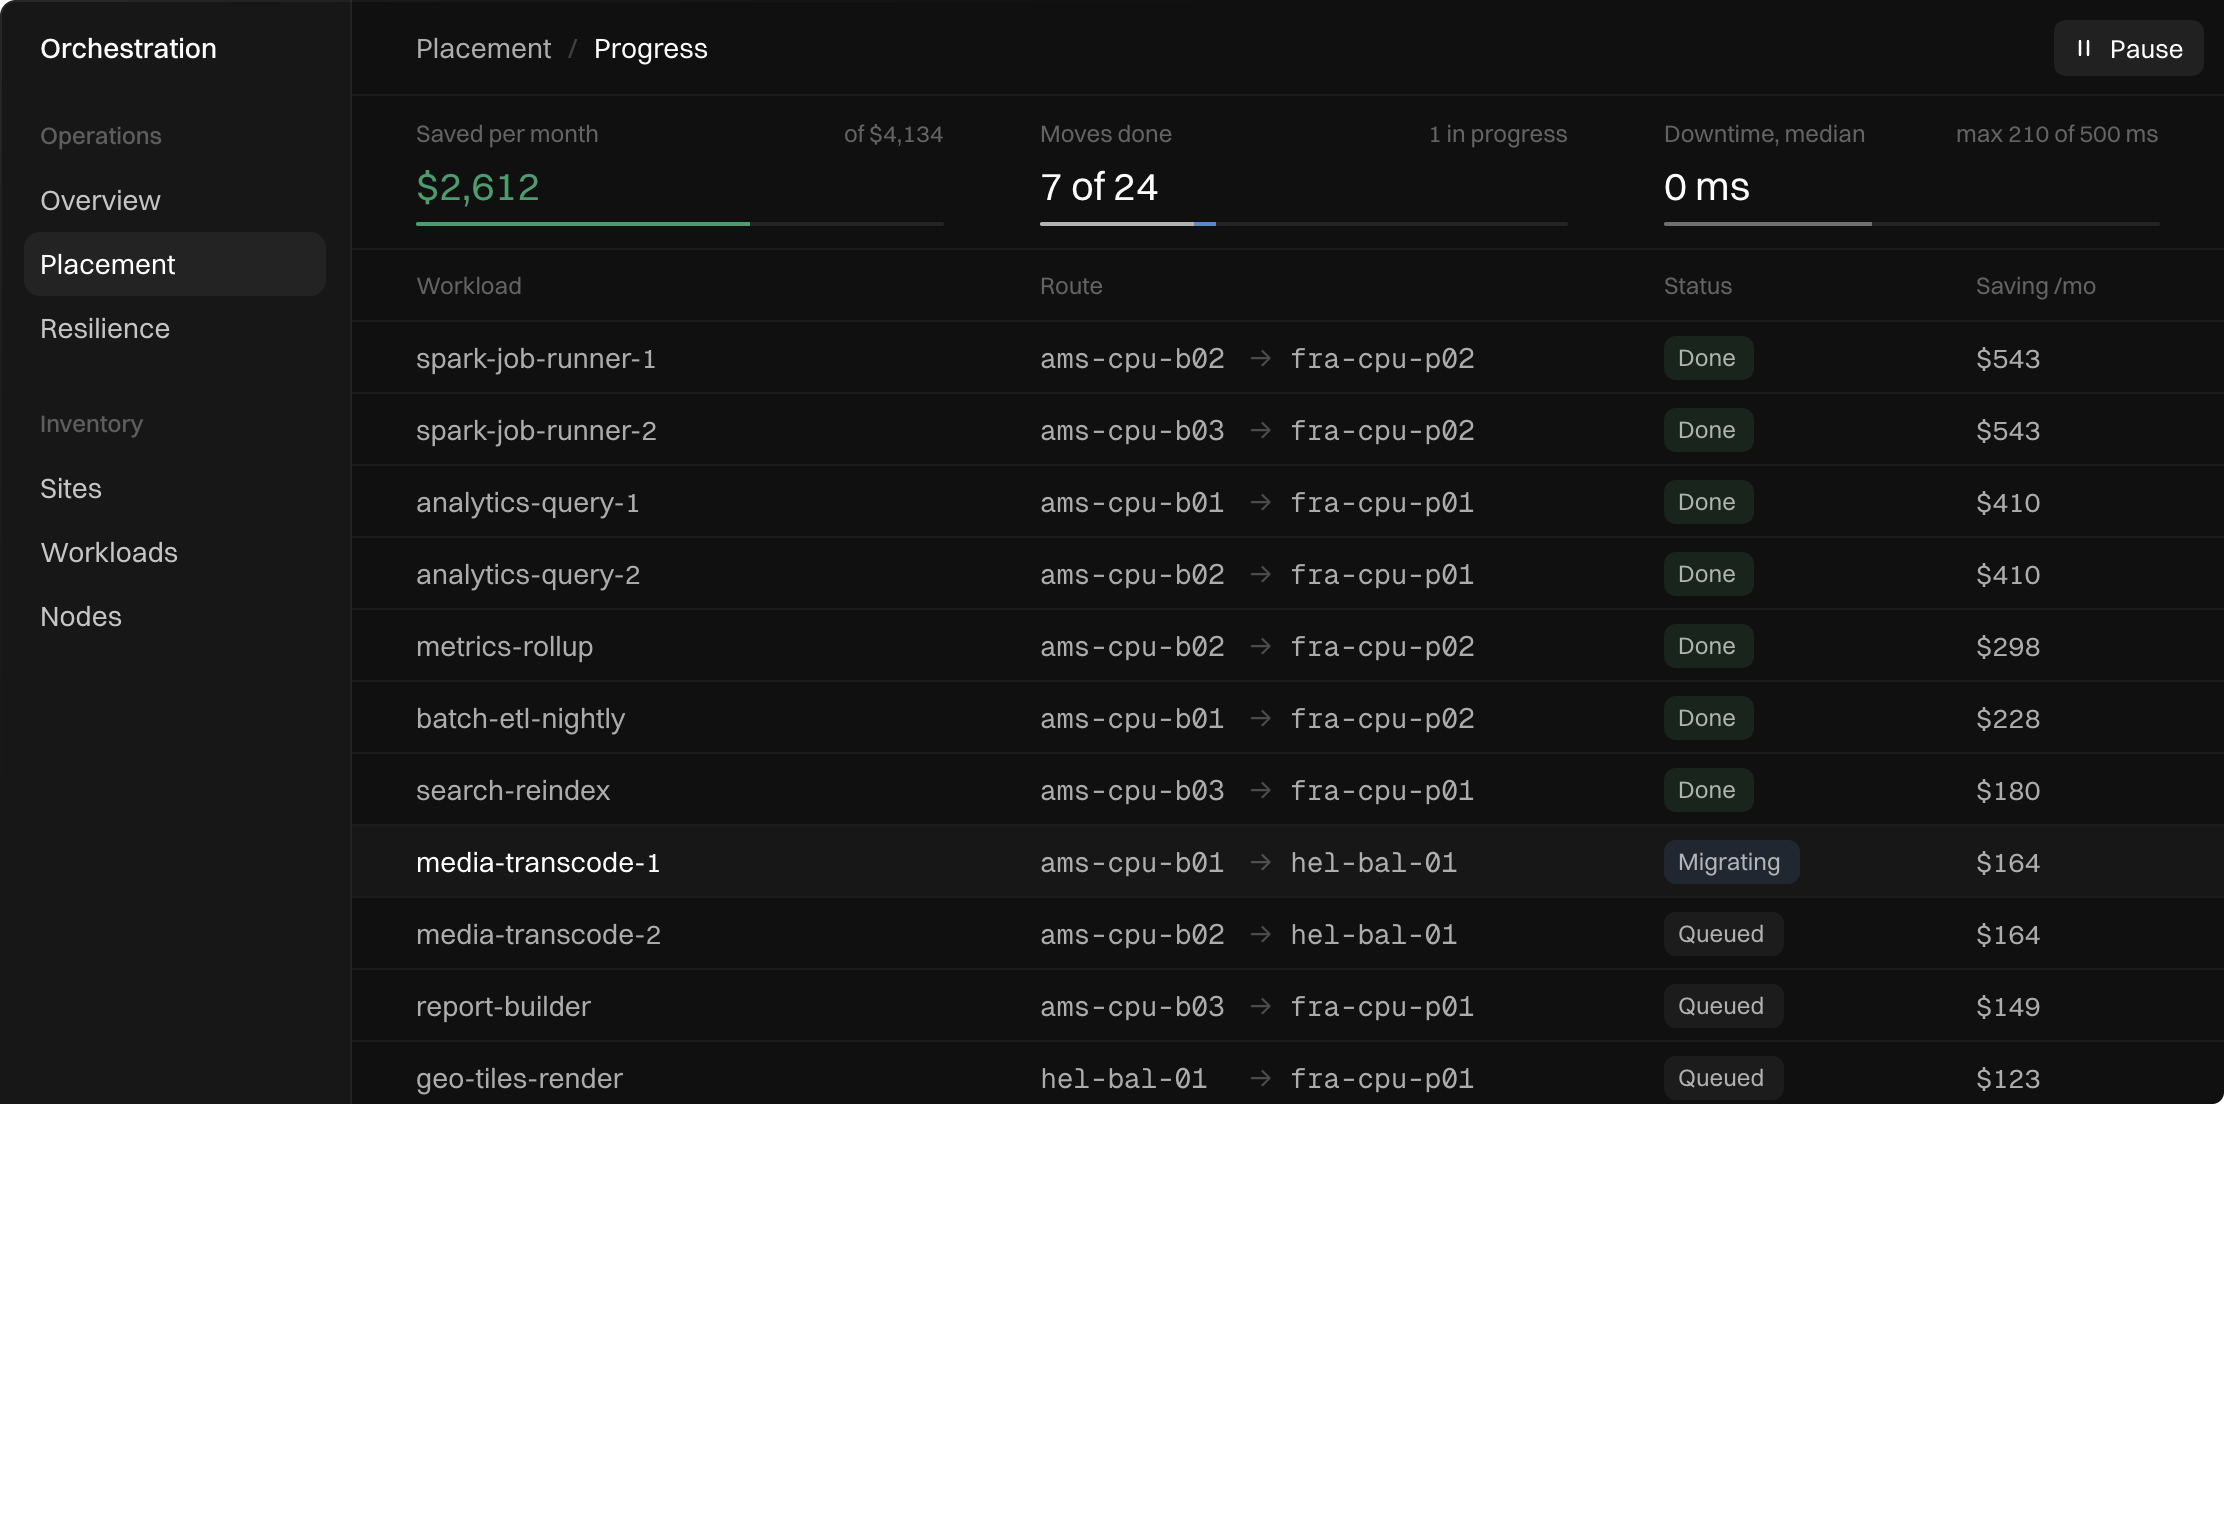
Each site operates on its own and coordinates with other sites peer to peer. If one site fails, the others take over its applications.
Adaptive scheduling
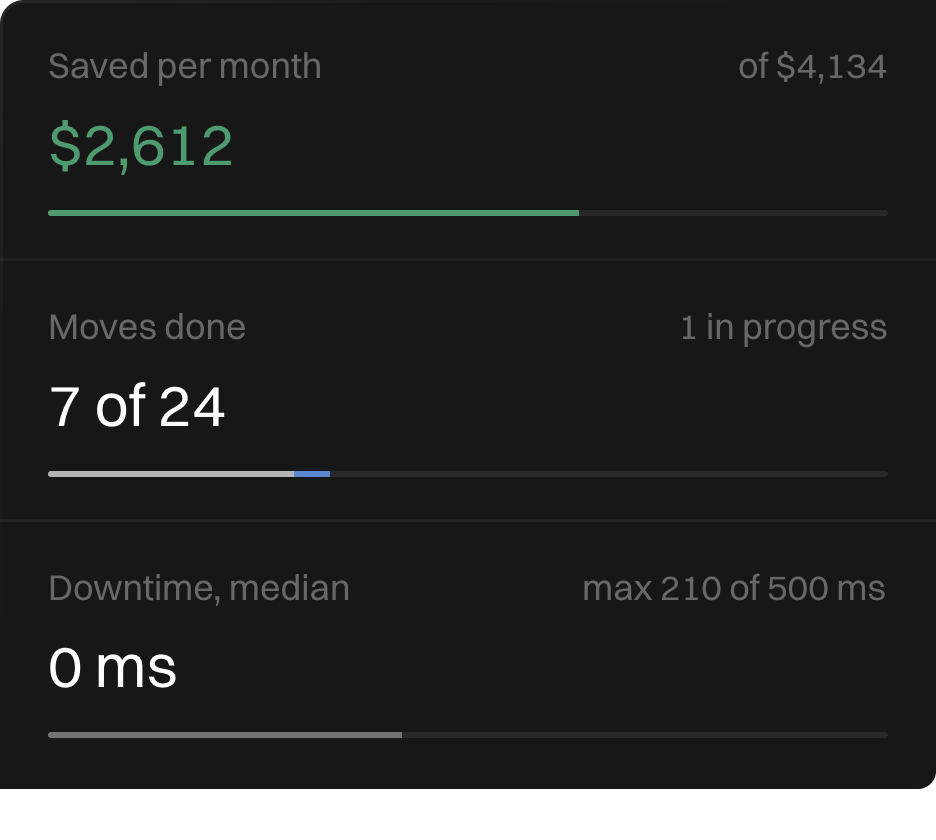
Maintain application performance by moving workloads away from overloaded or unhealthy nodes.
Automatic rightsizing
Free up capacity for other applications by adjusting resource allocations to actual usage.
Predictive autoscaling
Maintain performance and uptime by scaling capacity before demand spikes.
Shared data catalogue
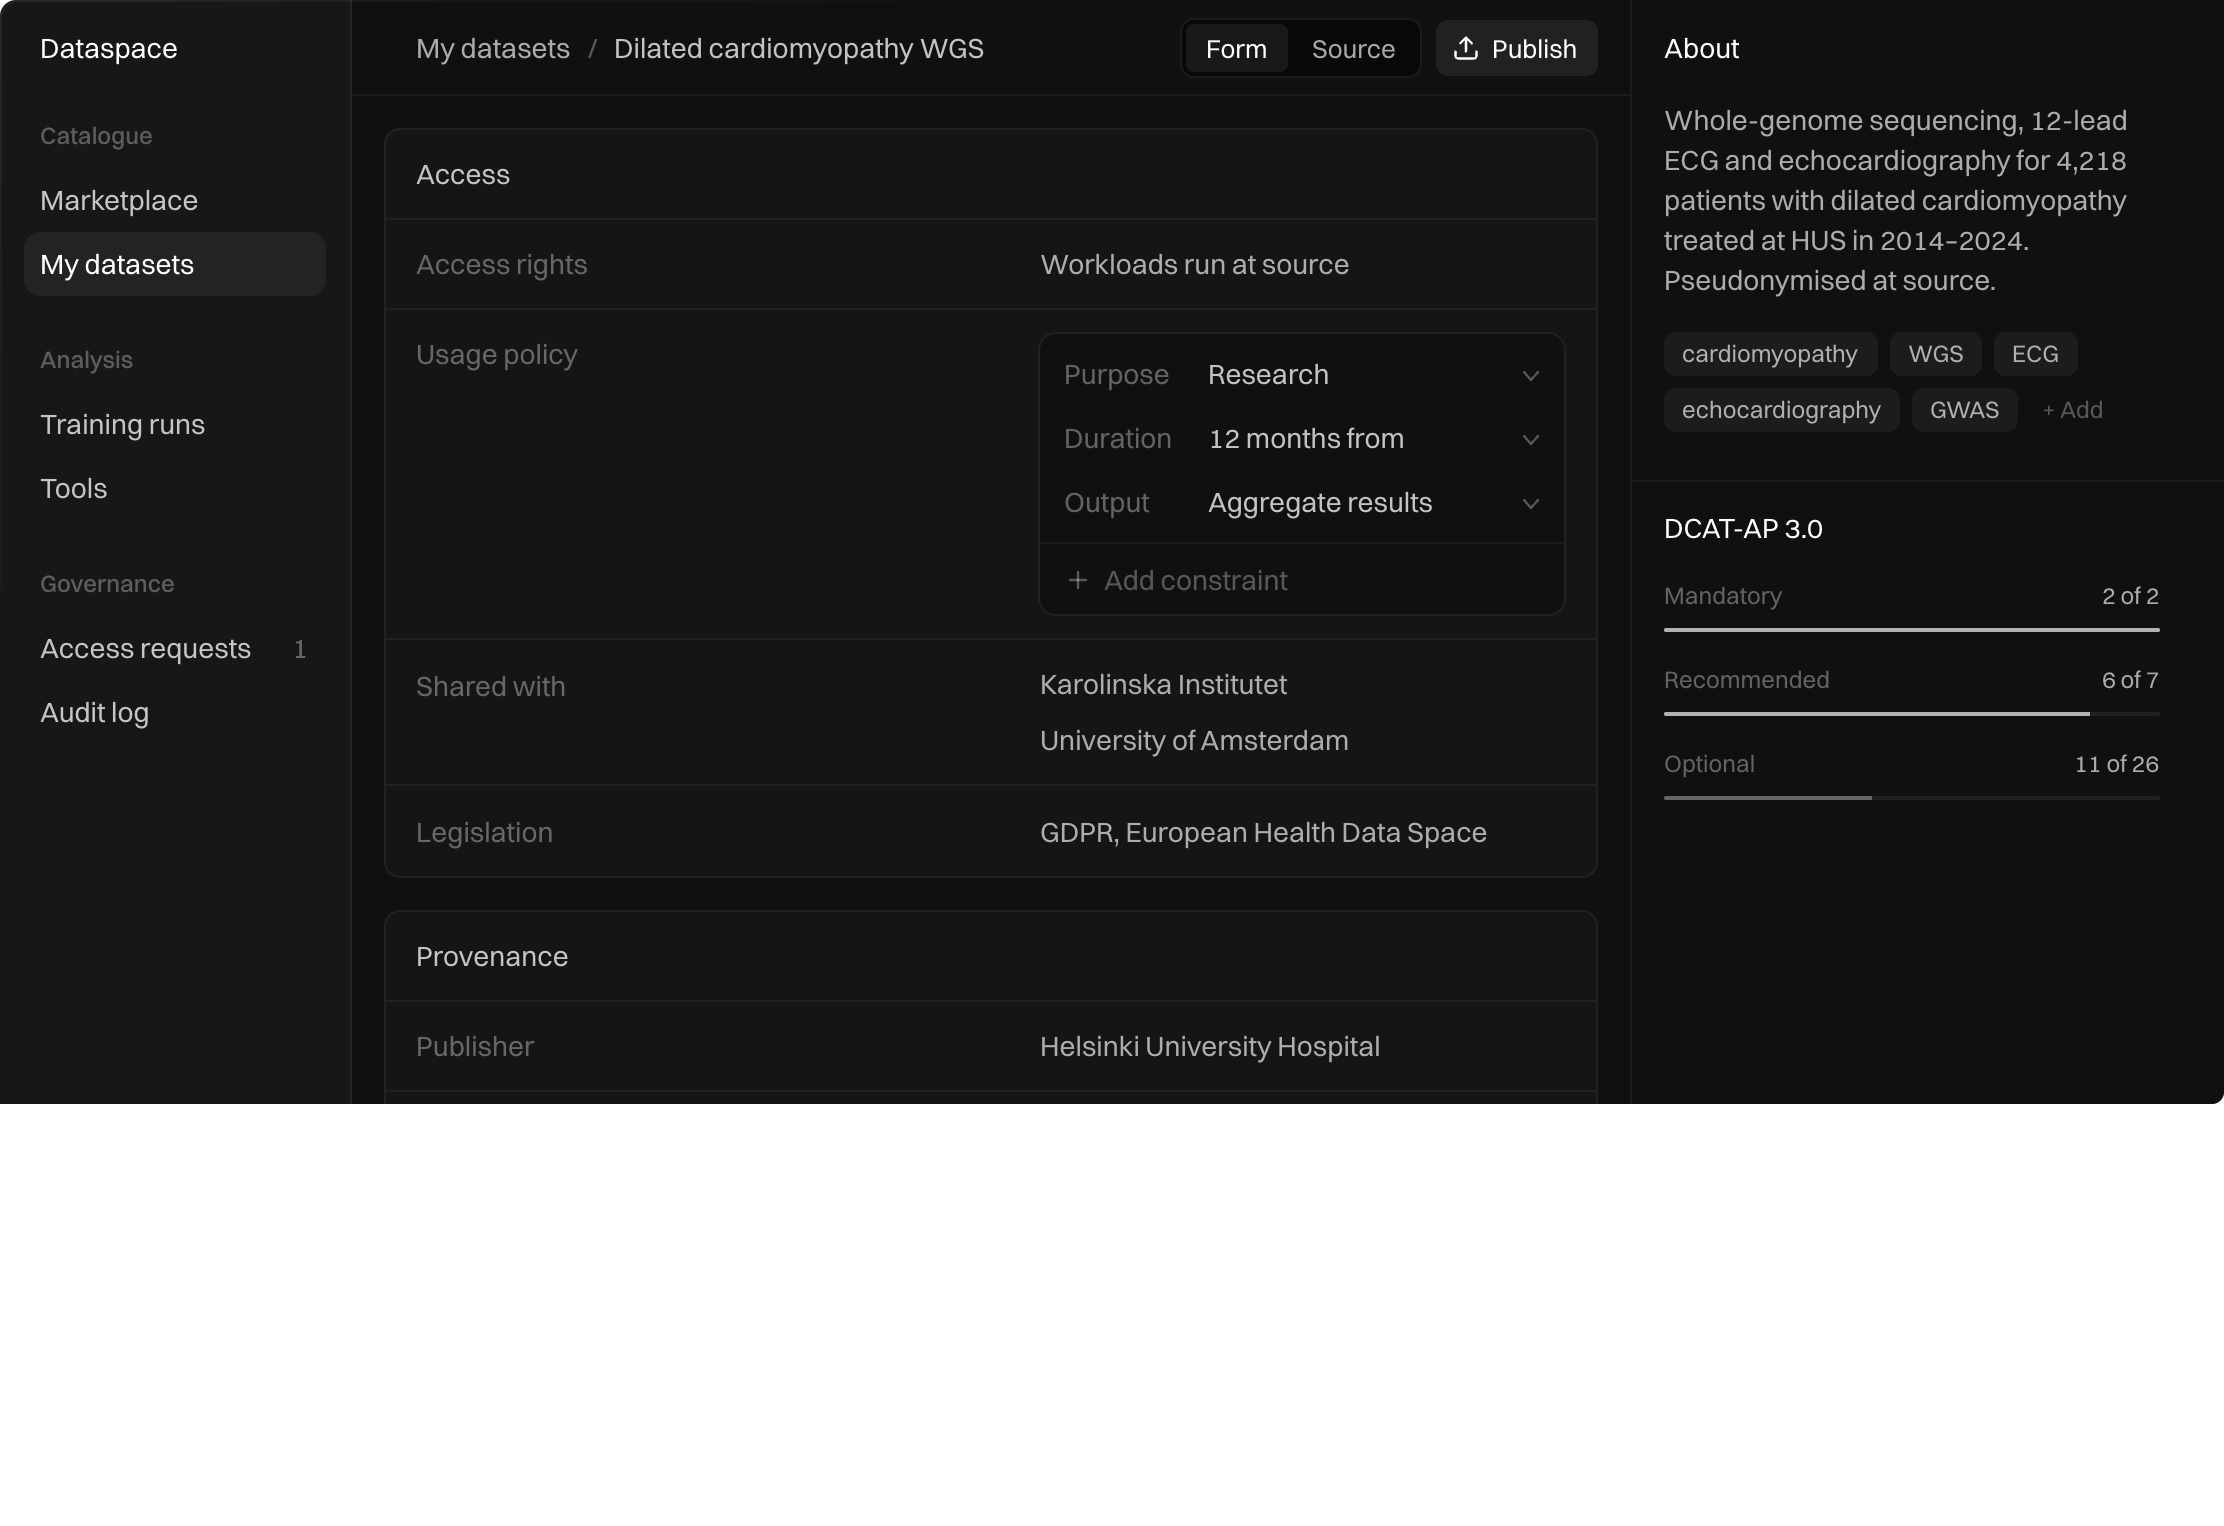
Find training data across biobanks and partner organisation, with clear usage terms and descriptions.
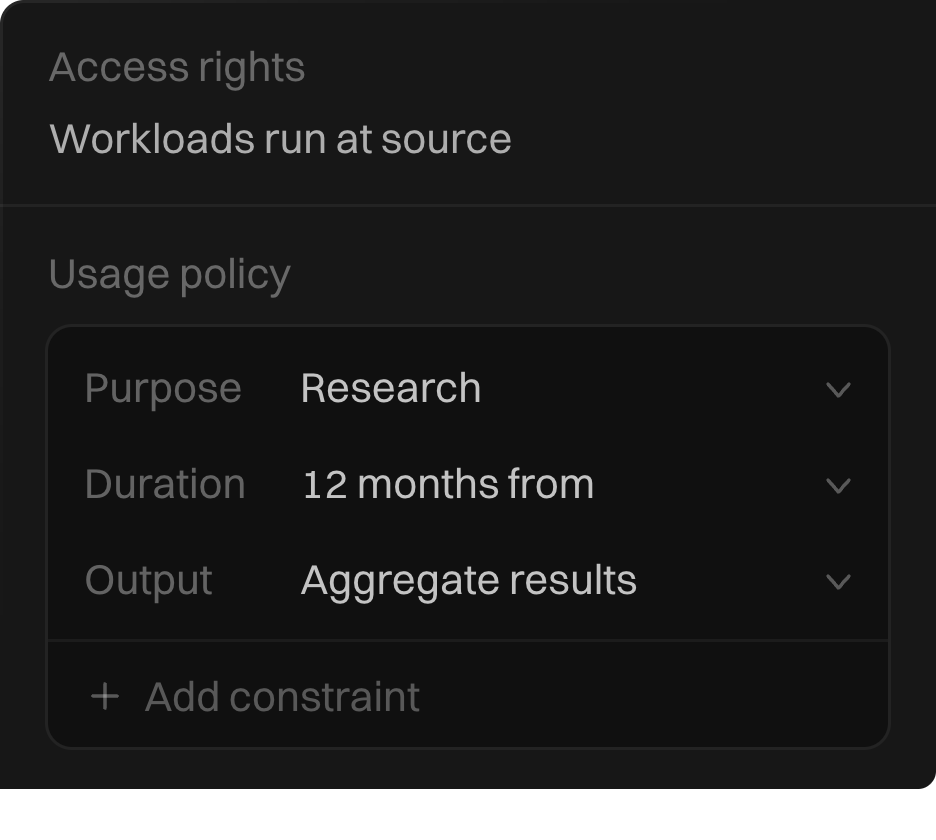
Owner-defined access
Let partners work with your data within limits you set. Enforce permissions by role, organization, purpose and duration, and revoke access when needed.
Federated learning
Train models and run analysis on data partners cannot transfer. Approved workloads run at source, under the owner’s rules.
Immutable audit trail
Account for data use in audits and internal reviews with encrypted records of access, queries and exports.
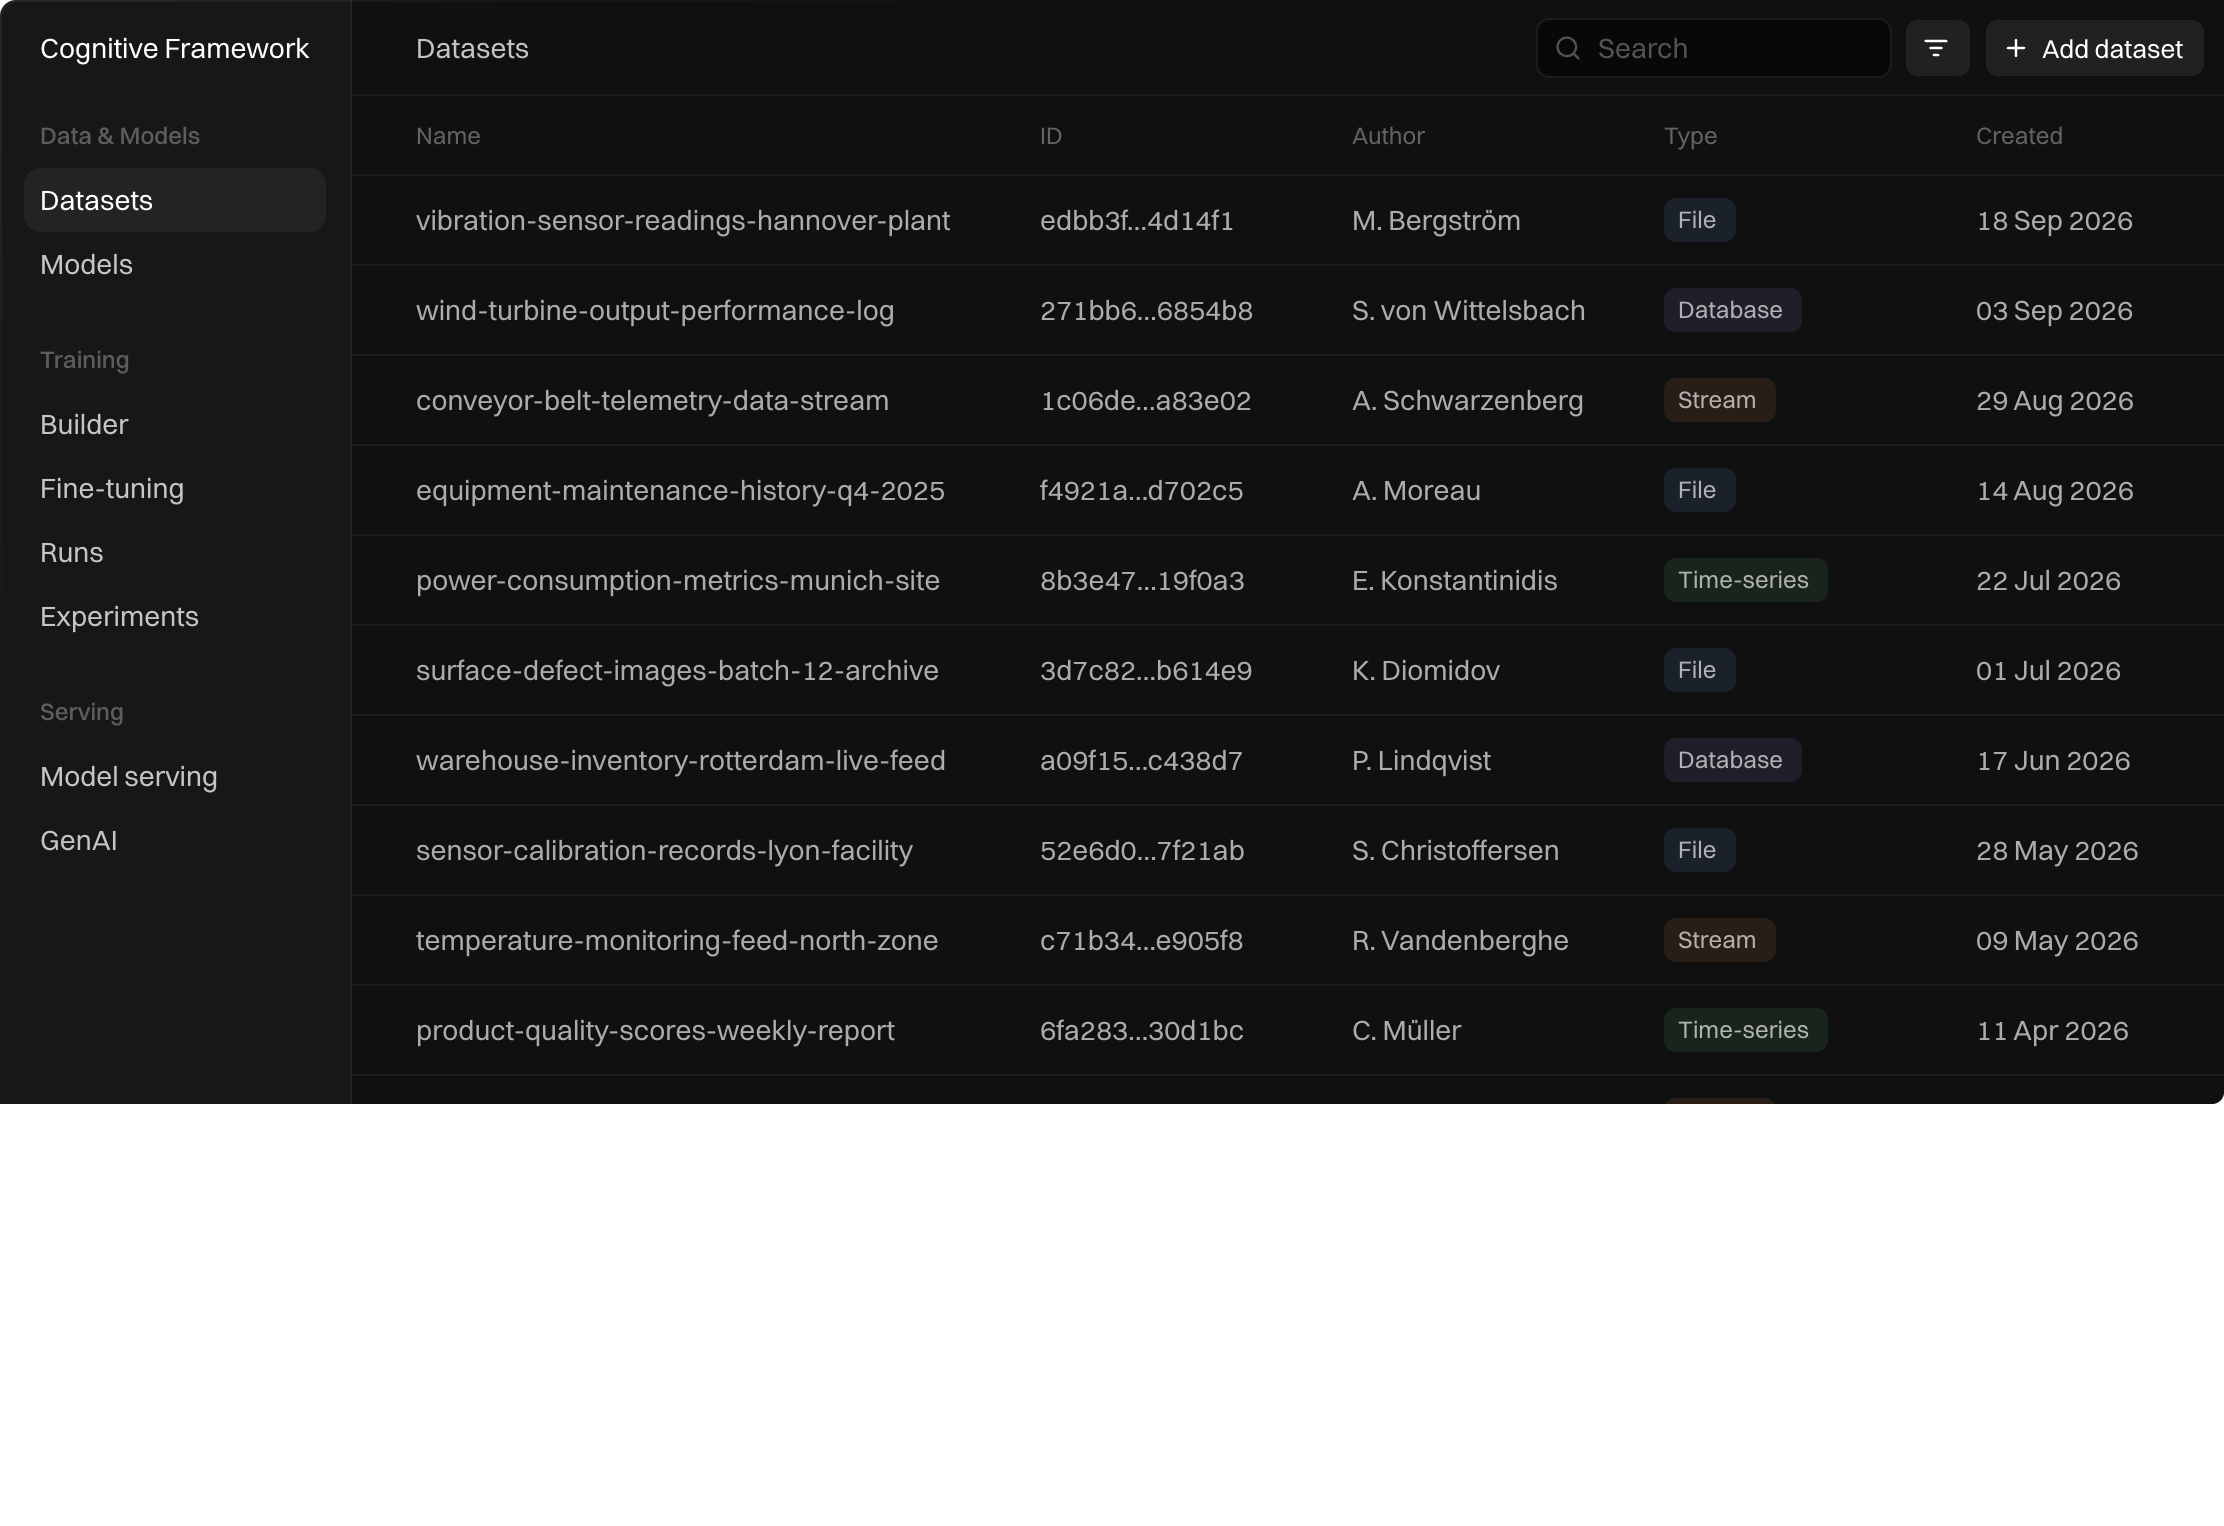
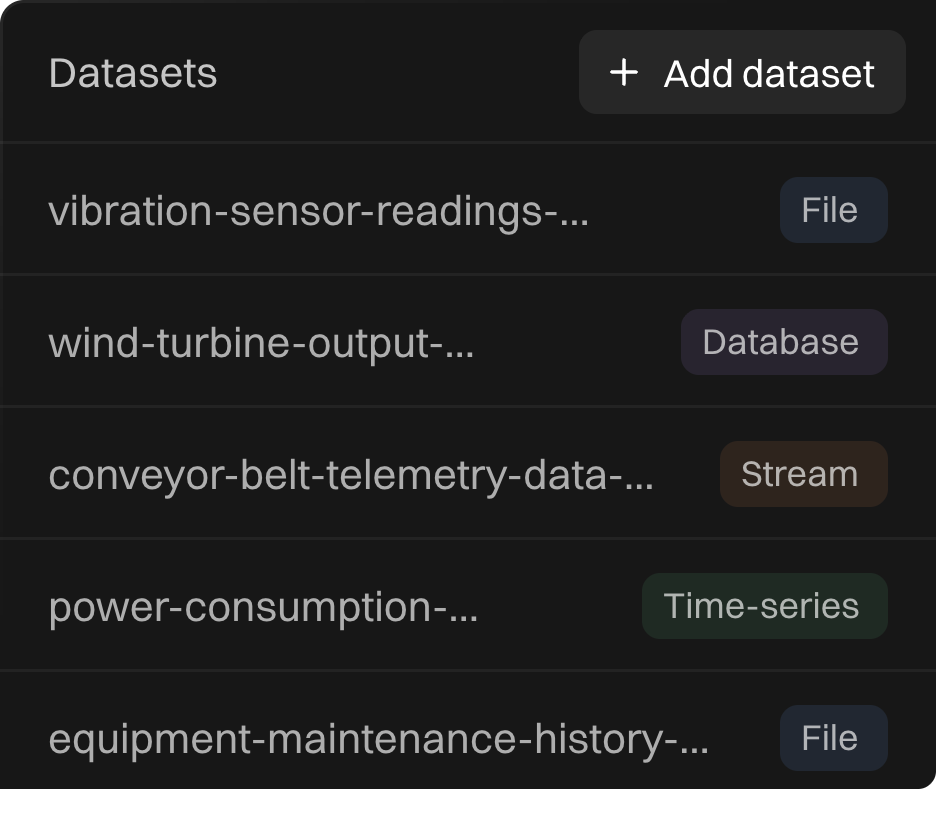
Dataset and model versioning
Keep datasets, models and training history organised, with each model version linked to the dataset, parameters and pipeline used in training.
Reusable training workflows
Improve models through repeatable experiments: adapt existing workflows and compare parameters, metrics and results to see what works best.
Hardware-aware deployments
Serve models to your applications on your own infrastructure, with compute and memory sized to each model’s requirements.
Controlled model updates
Keep applications running during model updates with canary rollouts, performance monitoring and quick rollbacks.

Nextgen
Training AI on hospital data without exposing patient records

Glaciation
Distributing data processing for Italy’s national payroll service

ACES
Extending power-grid analytics across distributed edge infrastructure
CAPE
Building edge infrastructure that can evolve without a full rebuild

Shift2DC
Reducing power losses in edge data centers with direct current

MYRTUS
Keeping distributed data consistent from edge to cloud

SYCLOPS
Keeping AI acceleration open and portable across hardware platforms

BRAINE
Bringing data-center capacity to the network edge

OptimAIse
Running generative AI efficiently on European hardware
VERGE
VERGE
Running secure, explainable AI on 5G edge infrastructure