
Collaborating with industry leaders


HIRO PEaaS STACK
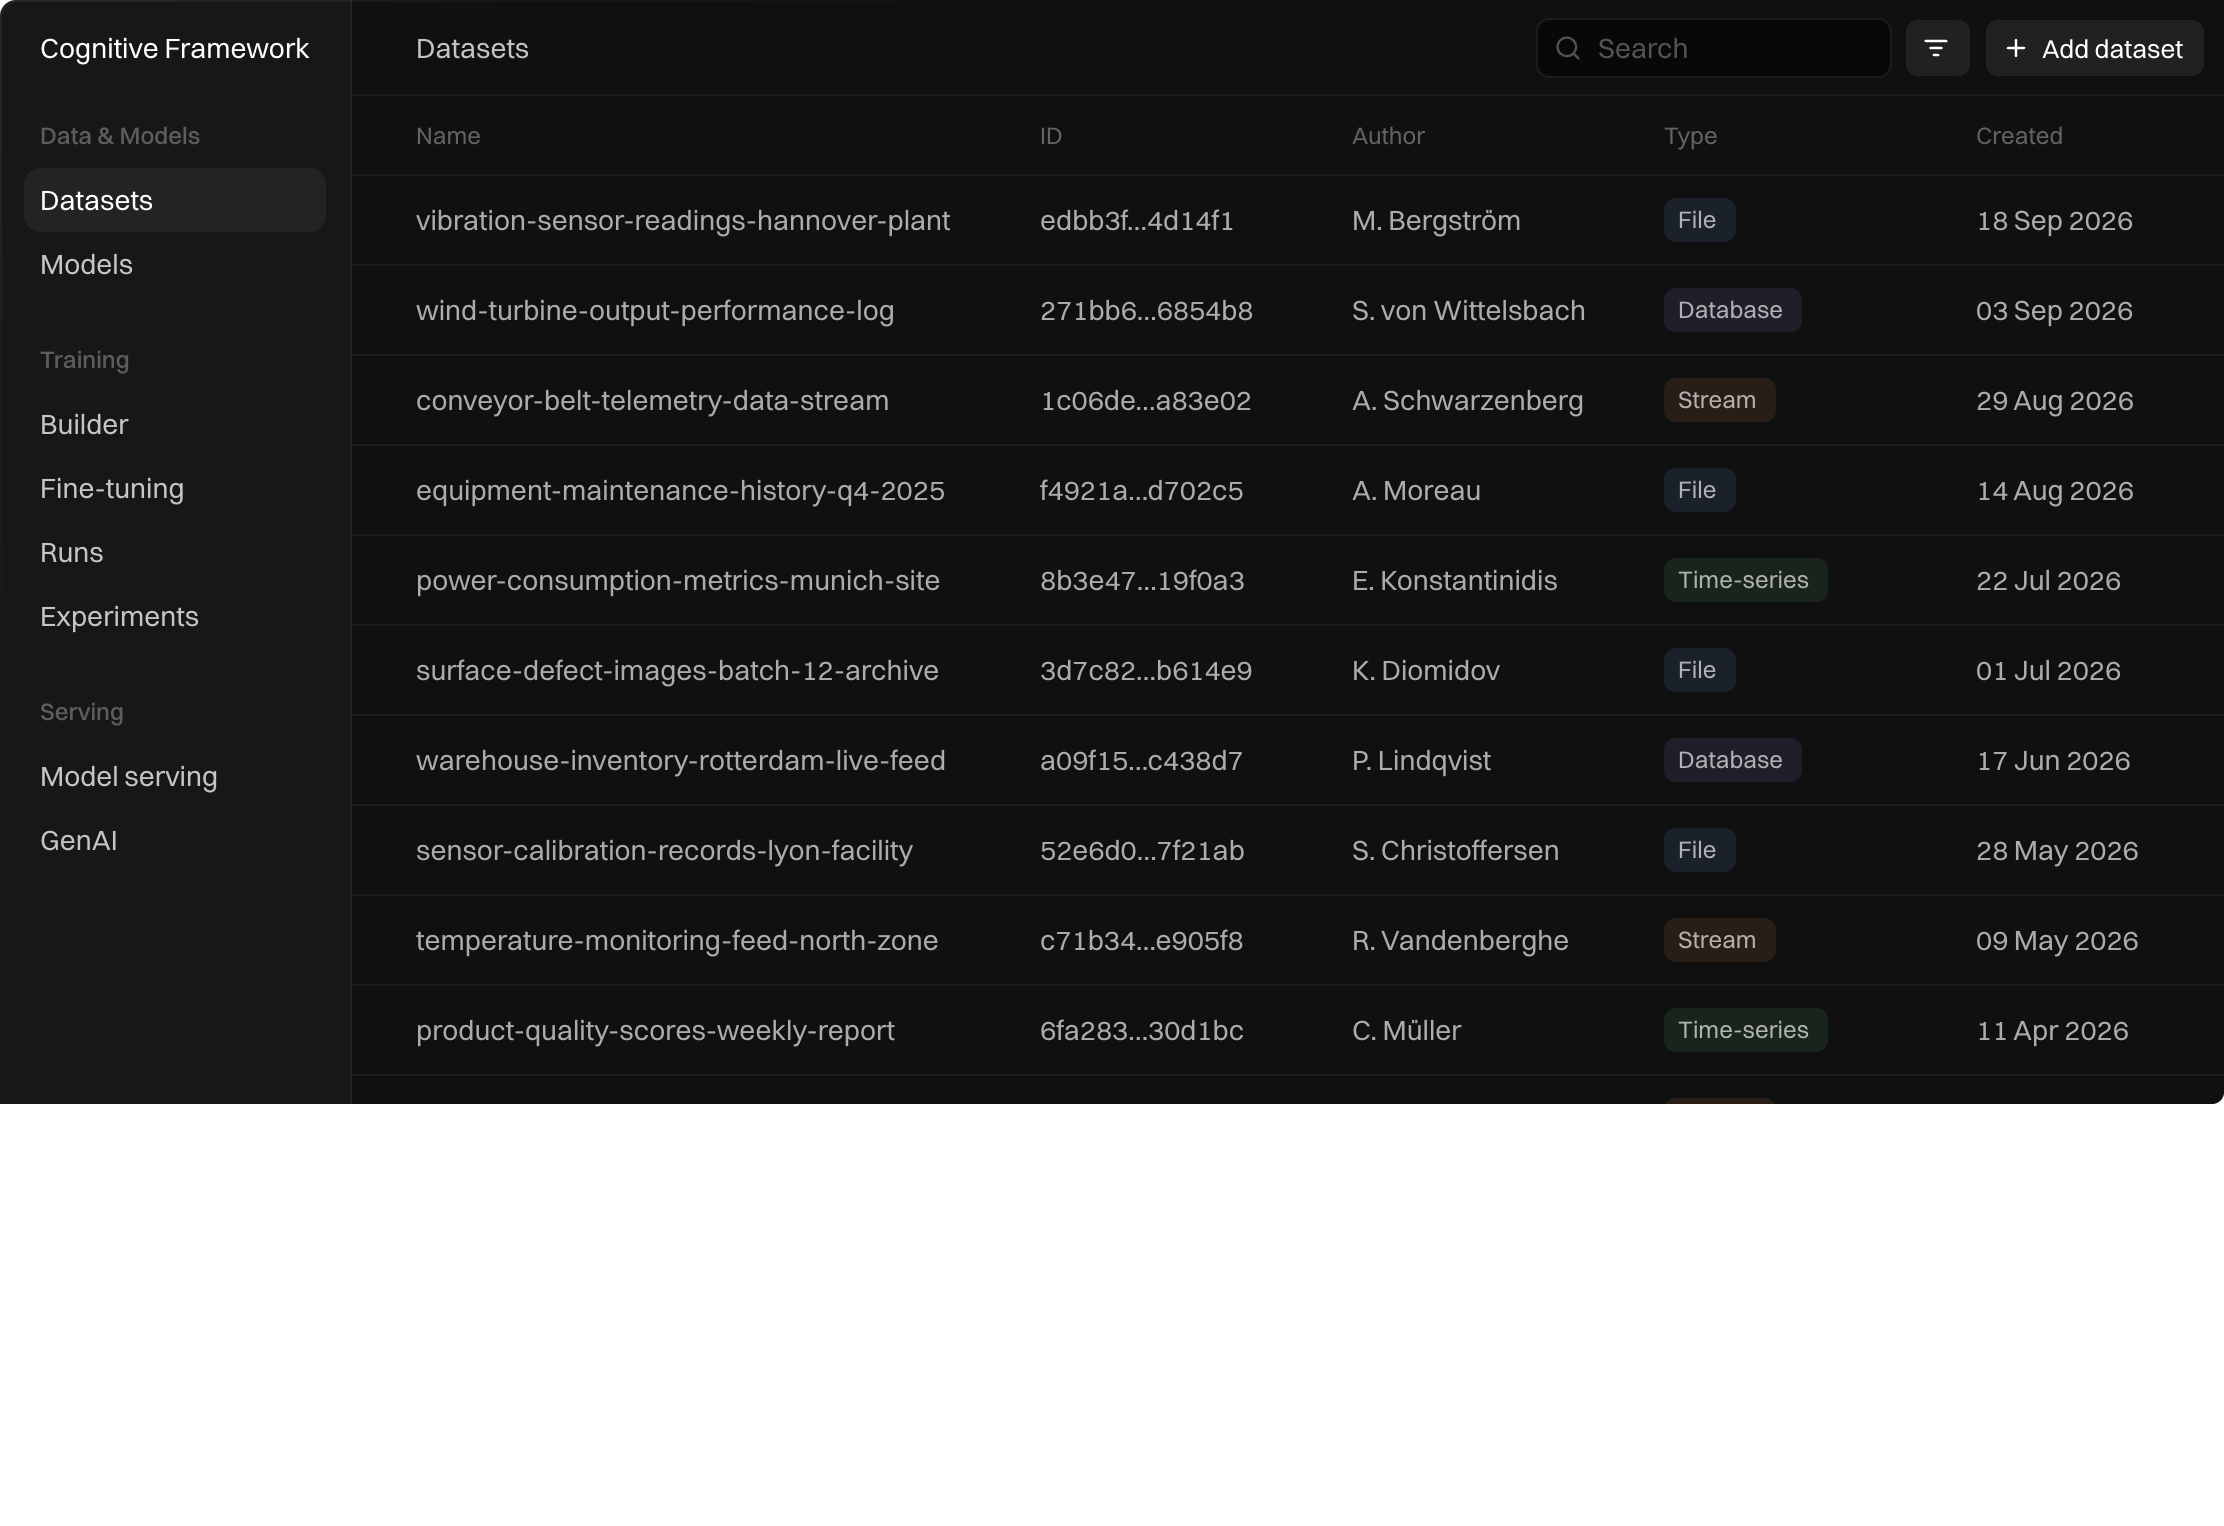
Dataset and model versioning
Keep datasets, models and training history organised, with each model version linked to the dataset, parameters and pipeline used in training.
Reusable training workflows
Improve models through repeatable experiments: adapt existing workflows and compare parameters, metrics and results to see what works best.
Hardware-aware deployments
Serve models to your applications on your own infrastructure, with compute and memory sized to each model’s requirements.
Controlled model updates
Keep applications running during model updates with canary rollouts, performance monitoring and quick rollbacks.
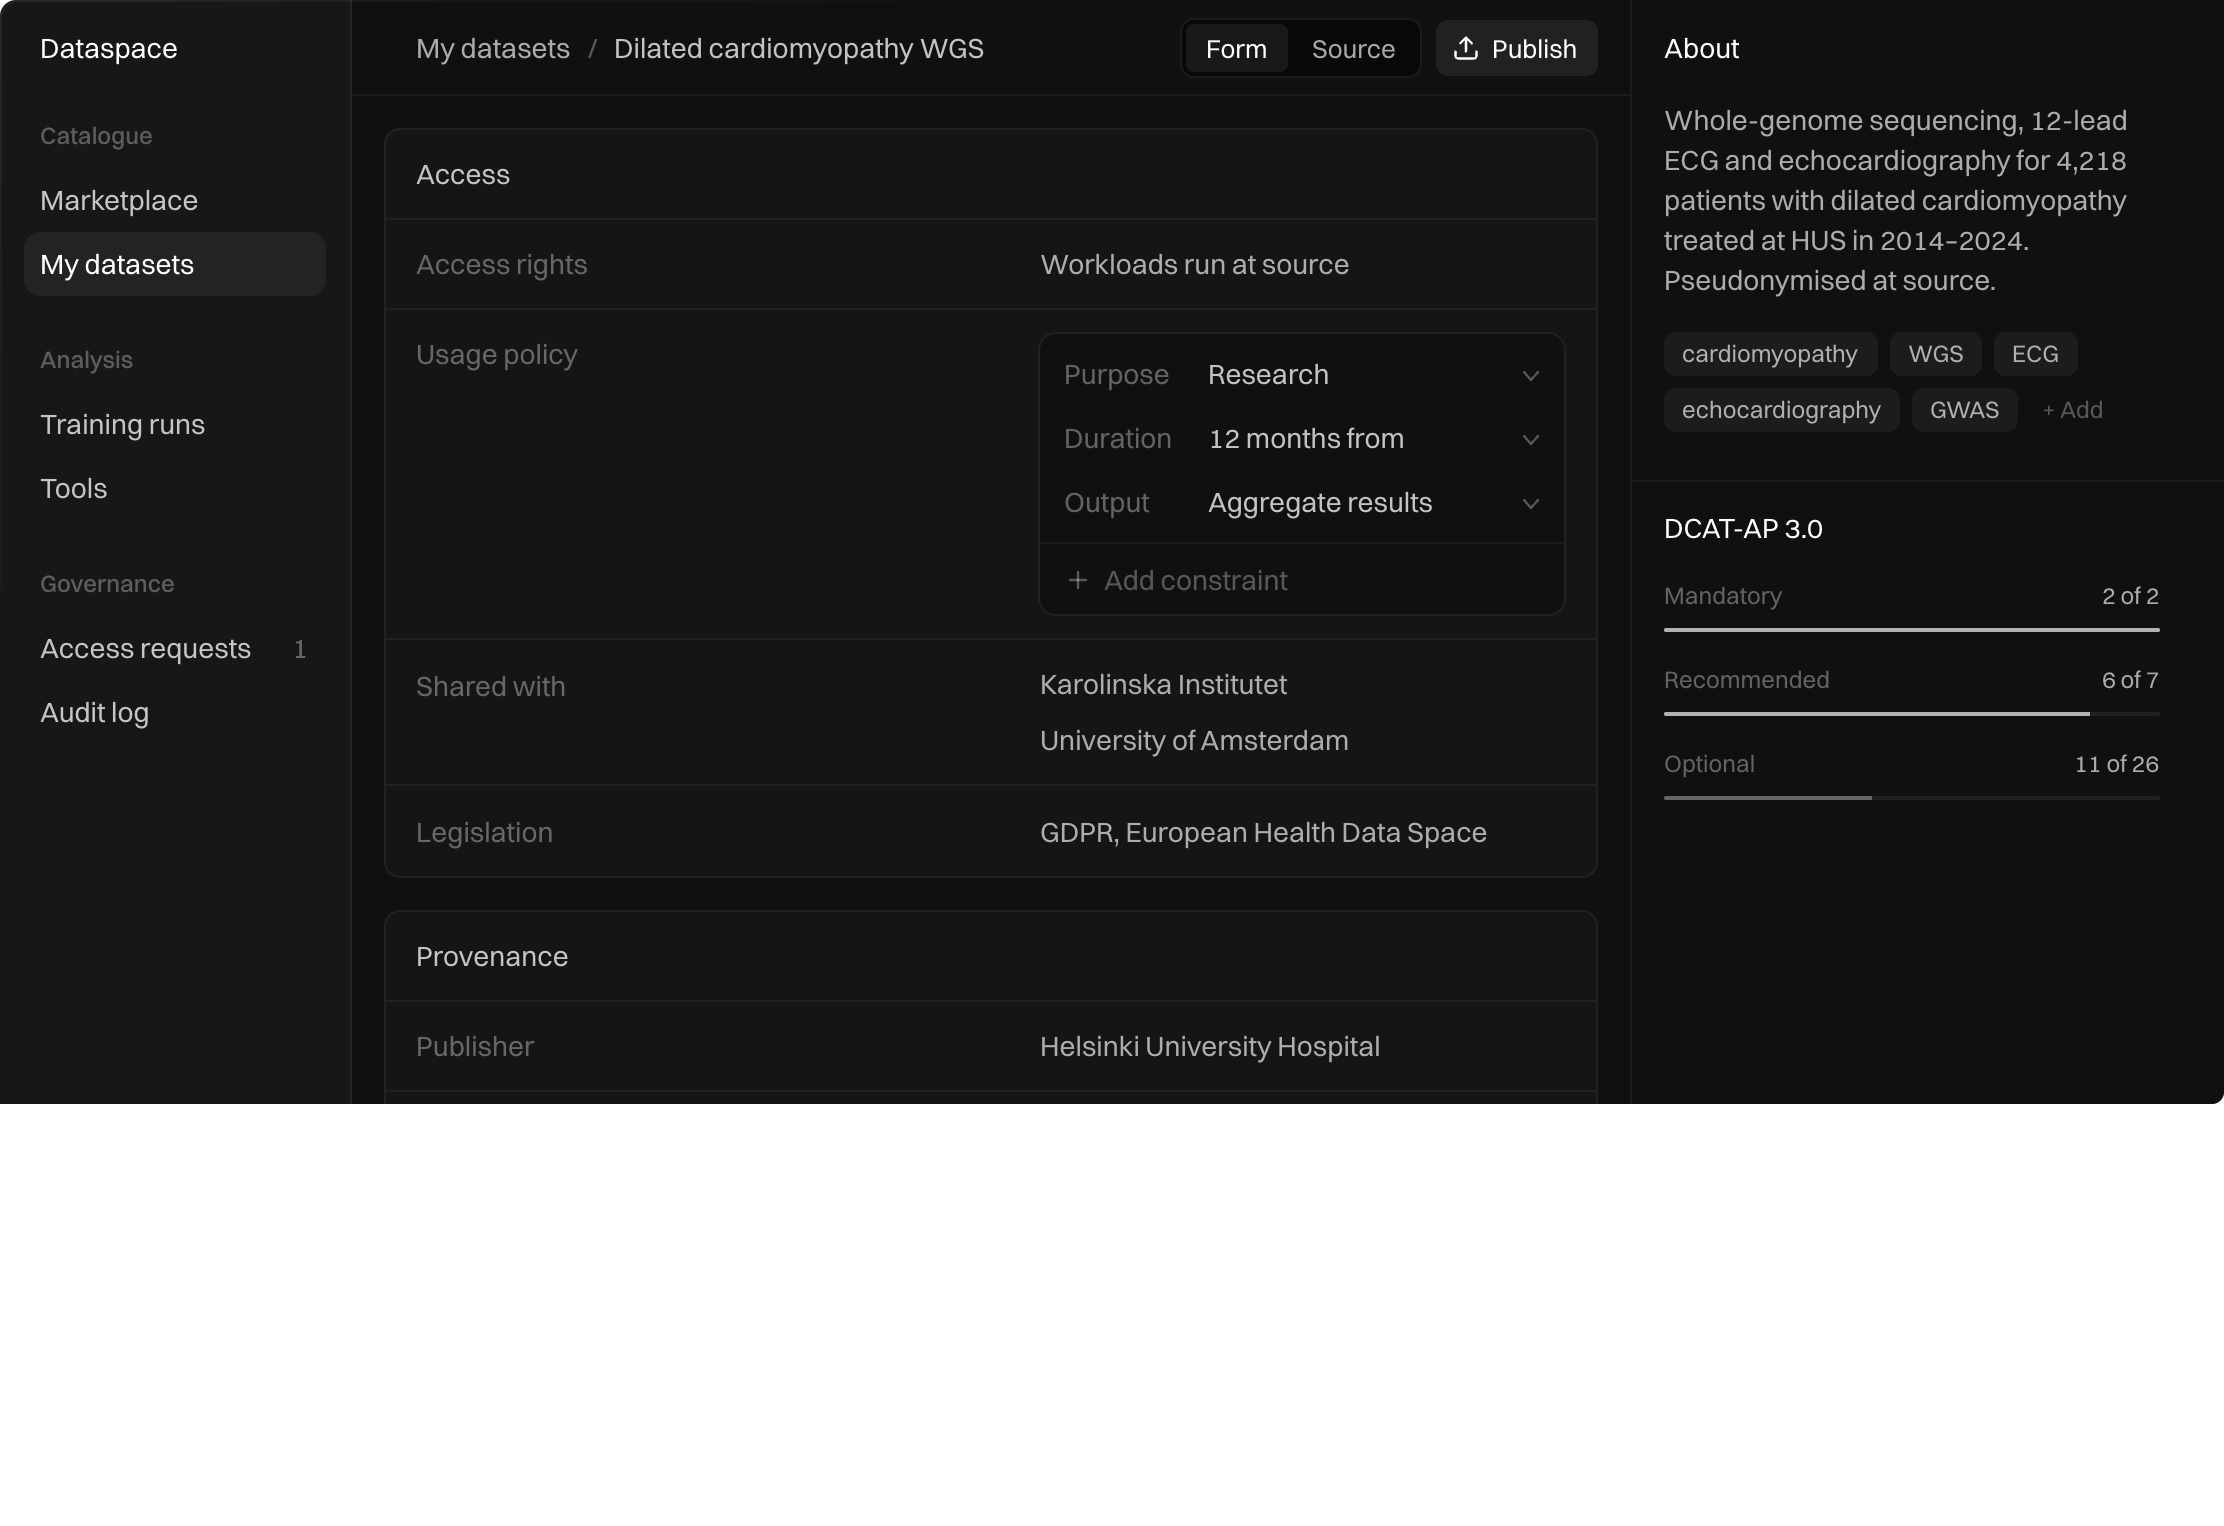
Shared data catalogue
Find training data across biobanks and partner organisation, with clear usage terms and descriptions.
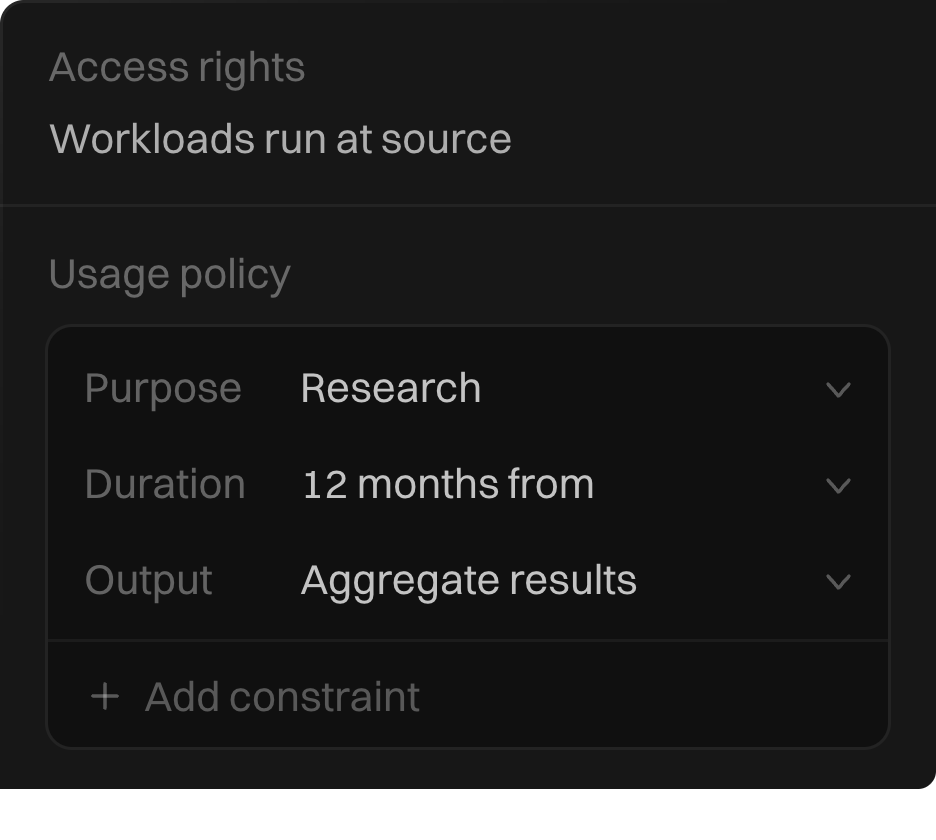
Owner-defined access
Let partners work with your data within limits you set. Enforce permissions by role, organization, purpose and duration, and revoke access when needed.
Federated learning
Train models and run analysis on data partners cannot transfer. Approved workloads run at source, under the owner’s rules.
Immutable audit trail
Account for data use in audits and internal reviews with encrypted records of access, queries and exports.
Autonomous sites
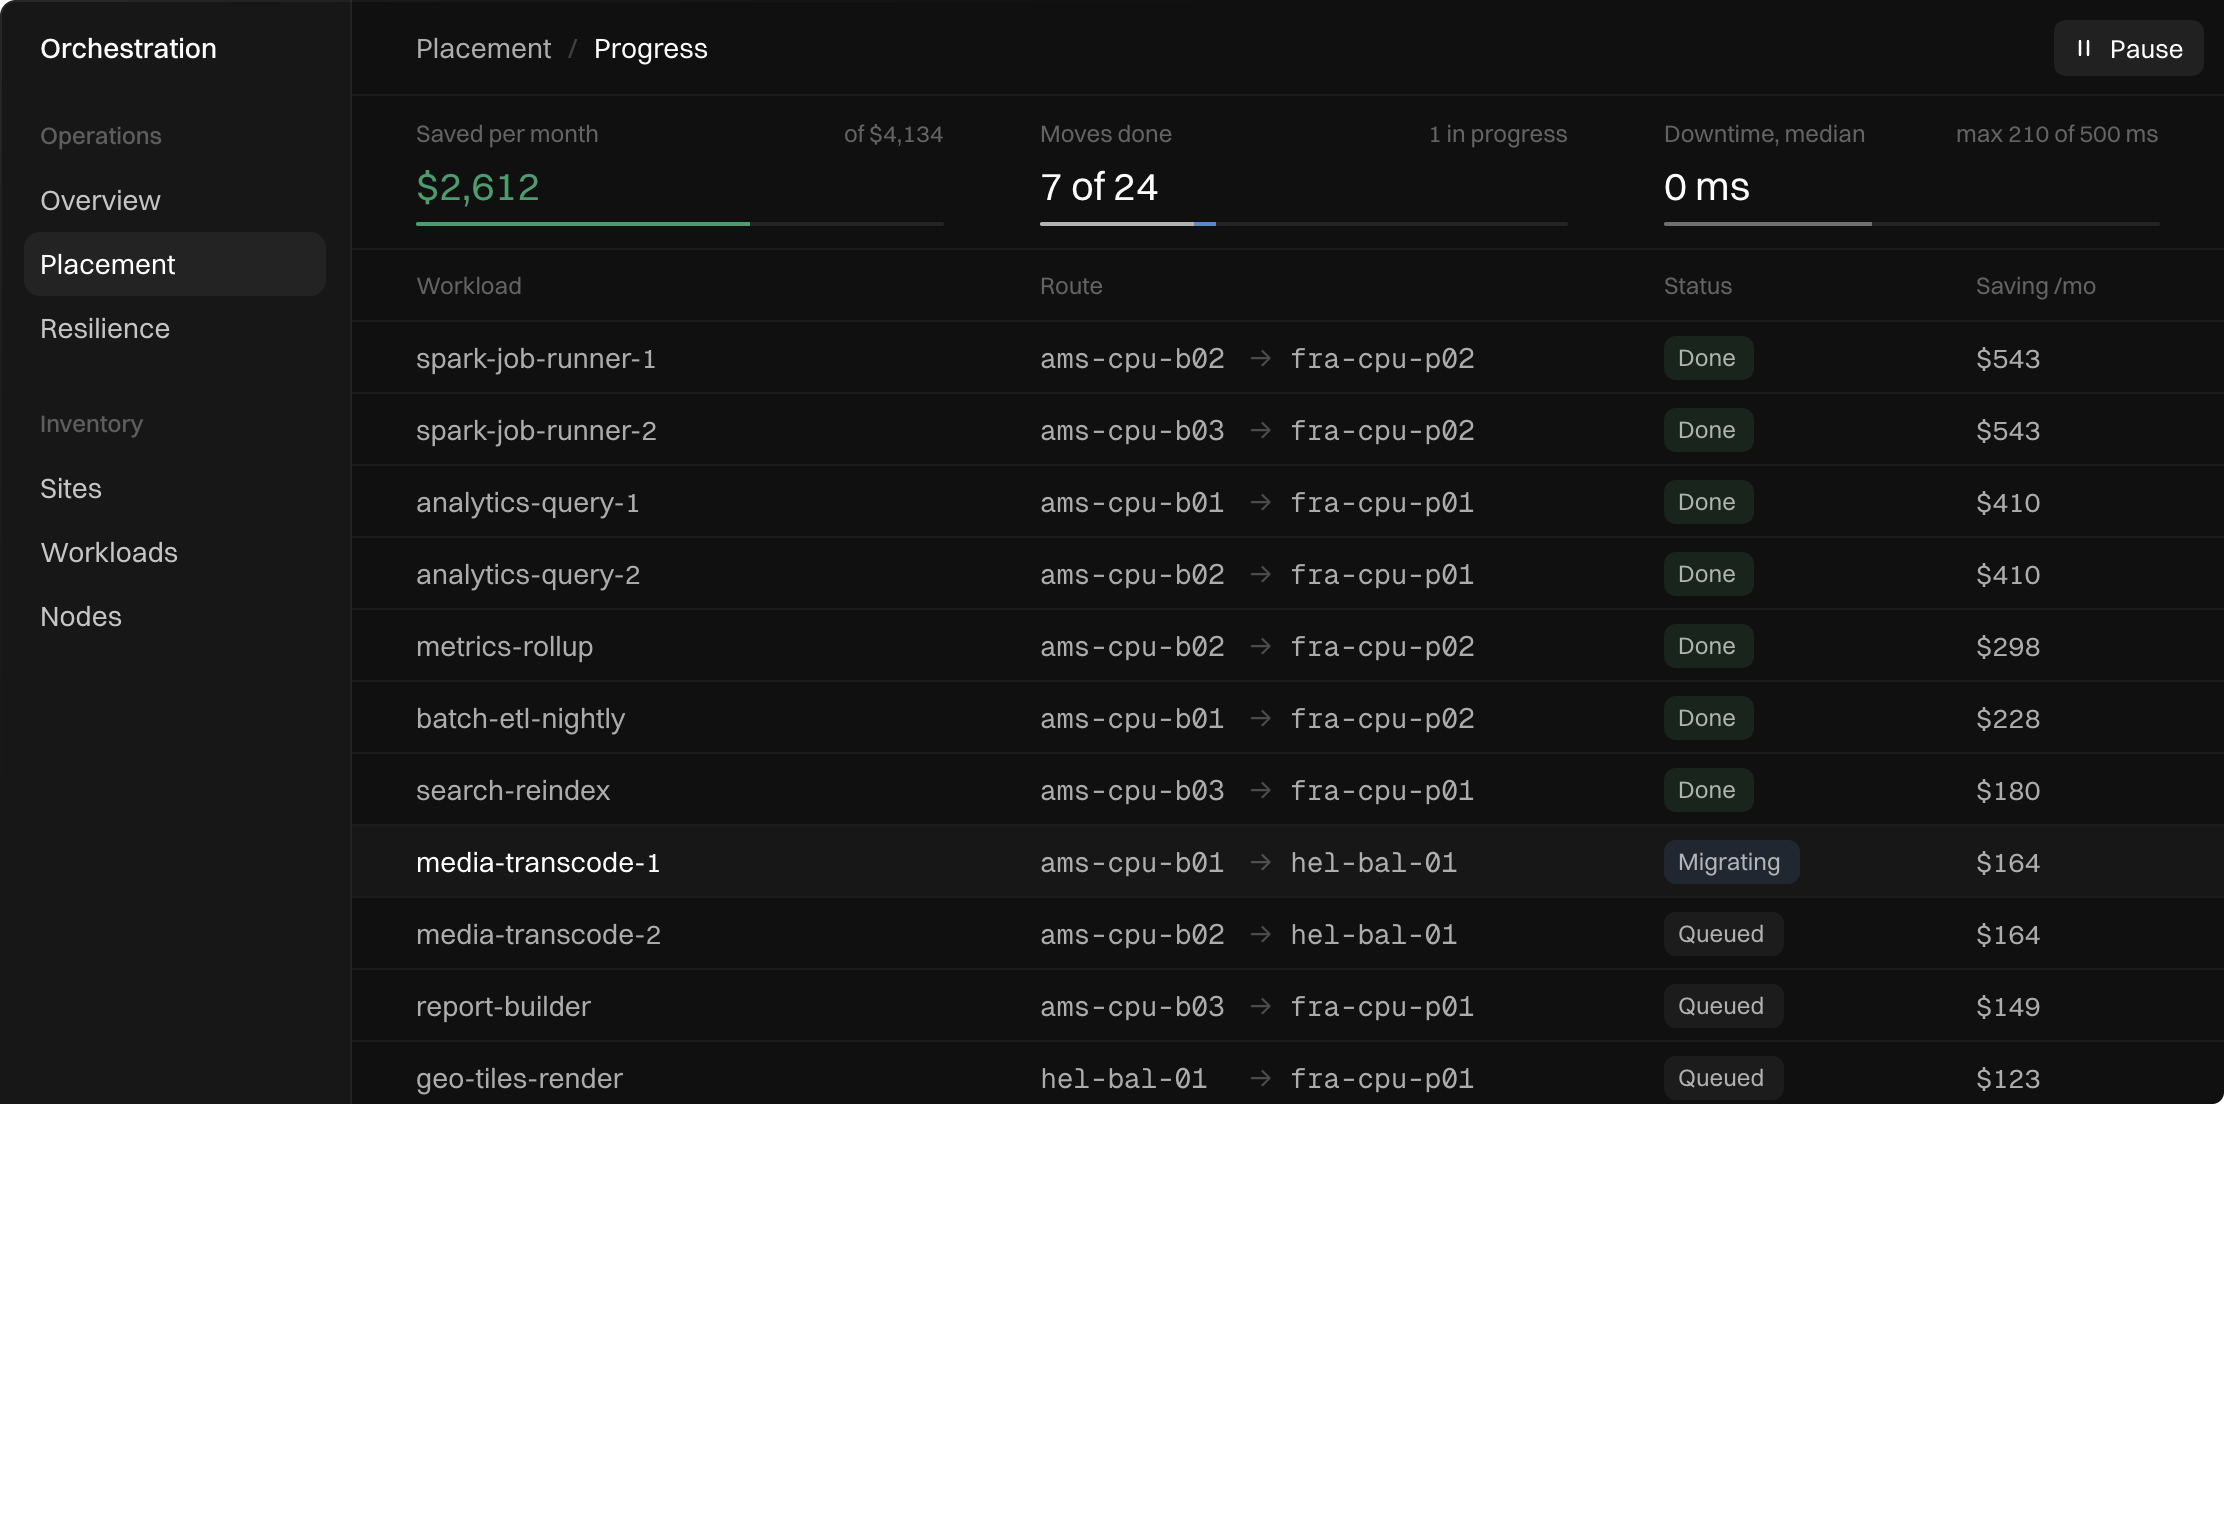
Operate each site independently, with local workload management and recovery. A peer-to-peer control plane coordinates work between sites.
Adaptive scheduling
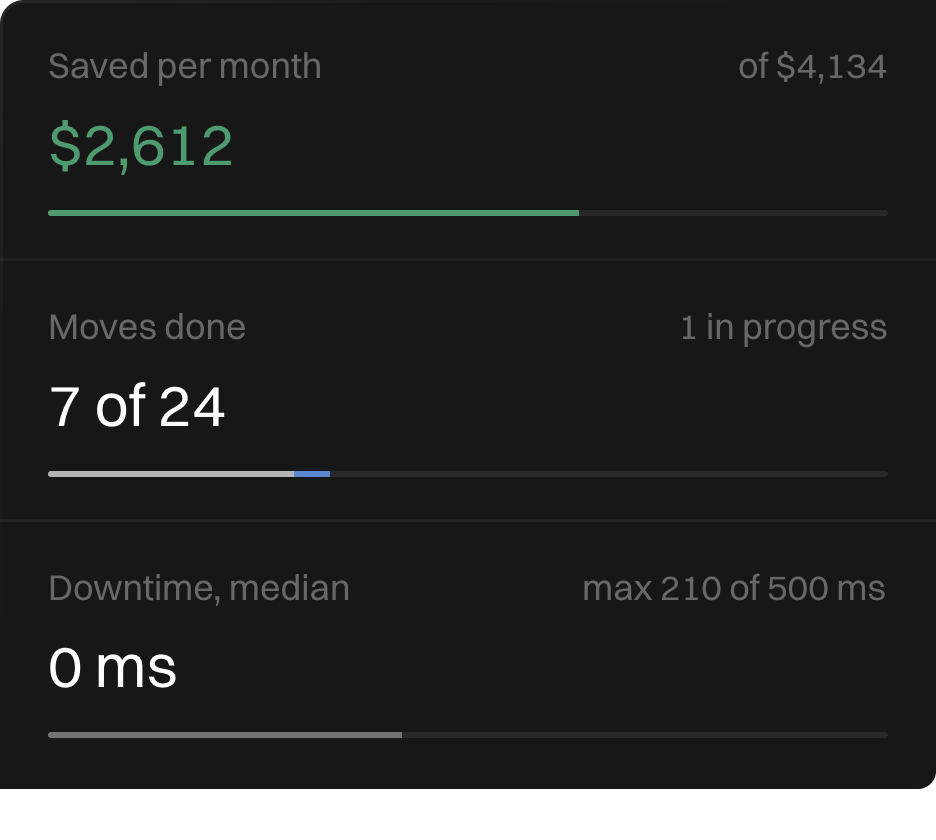
Maintain application performance by moving workloads away from overloaded or unhealthy nodes.
Automatic rightsizing
Free up capacity for other applications by adjusting resource allocations to actual usage.
Predictive autoscaling
Maintain performance and uptime by scaling capacity before demand spikes.

Nextgen
Training AI on hospital data without exposing patient records

Glaciation
Distributing data processing for Italy’s national payroll service

ACES
Extending power-grid analytics across distributed edge infrastructure
CAPE
Building edge infrastructure that can evolve without a full rebuild

Shift2DC
Reducing power losses in edge data centers with direct current

MYRTUS
Keeping distributed data consistent from edge to cloud

SYCLOPS
Keeping AI acceleration open and portable across hardware platforms

BRAINE
Bringing data-center capacity to the network edge